
Best 12 Steps to Create an OT Change Control Process
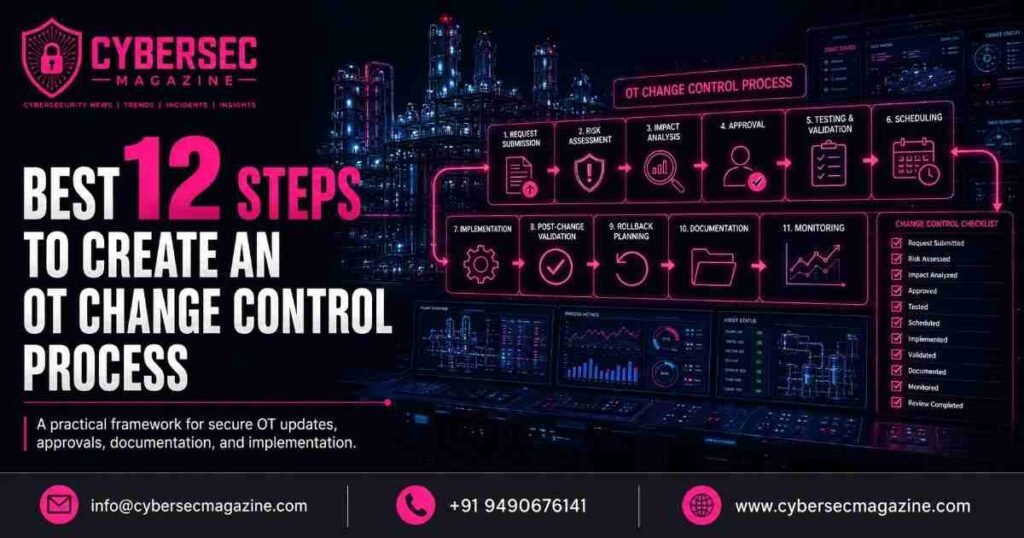
As global industrial environments face mounting cyber-physical threats, traditional IT-style change management is no longer sufficient for Operational Technology (OT), Industrial Control Systems (ICS), and Medical IoT (MIoT) networks. In enterprise IT, a botched software update might cause a temporary database timeout; in an industrial plant, an unvetted configuration change to a programmable logic controller (PLC) or human-machine interface (HMI) can trigger catastrophic equipment damage, environmental hazards, or severe safety incidents. Under regulatory frameworks like the EU NIS2 Directive, NERC CIP, and IEC 62443, proving rigorous operational governance and change accountability is mandatory. Developing a specialized, secure change control process ensures that every plant-floor modification is meticulously tracked, tested, and authorized without jeopardizing real-time process availability. Below are the 12 essential steps to build a bulletproof OT change control process, with each step engineered to provide deep technical insights and distinct value for security leaders navigating modern compliance.
Best 12 Steps to Create an OT Change Control Process
1. Define Explicit Scope and Asset Boundaries Across Purdue Levels
Before any change management policy can function, organizations must establish a precise inventory of all assets spanning Purdue levels zero through four. This initial step requires mapping every legacy controller, smart sensor, RTU, and HMI workstation. Establishing clear boundaries ensures that the change control policy covers high-risk shop-floor loops differently from standard enterprise IT infrastructure, minimizing oversight gaps.
2. Establish a Cross-Functional Change Control Board (CCB)
OT change management cannot live solely within IT or plant engineering silos. A compliant Change Control Board must include representatives from cybersecurity, plant operations, automation engineering, and safety management. This multidisciplinary team evaluates proposed modifications through dual lenses: cyber risk reduction and physical process safety, preventing single-department blind spots from approving high-risk configuration tweaks.
3. Implement an OT-Tailored Request for Change (RFC) Workflow
Standard IT ticketing systems often fail to capture critical industrial data points. An OT-specific RFC template must require explicit fields detailing target PLC models, firmware versions, expected I/O register modifications, and potential process impacts. Requiring granular technical data prevents vague, high-level change requests from slipping through the review pipeline and ensures complete transparency before work begins.
4. Mandate Offline Pre-Testing and Sandbox Validation
Never test a configuration change or ladder logic update directly on live production machinery. Every proposed modification must be deployed first in a replicated staging environment or offline hardware sandbox. This step verifies that compiled binaries do not throw memory errors, trigger unexpected control loops, or cause communication timeouts, protecting physical machinery from unverified code execution.
5. Assess Security Level Impact and IEC 62443 Conformance
Every proposed modification must be evaluated against the facility’s baseline Security Level Target (SL-T) defined under IEC 62443-3-2. The change control review must explicitly verify that the modification does not weaken existing zone-and-conduit boundaries, bypass industrial firewalls, or introduce unmanaged vulnerabilities into critical control loops, maintaining rigorous regulatory posture.
6. Create Comprehensive Backout and Emergency Rollback Plans
Hope is not an operational strategy. Every approved change request must include a verified, step-by-step backout procedure. If a firmware patch or HMI screen update causes unexpected latency or process instability, plant engineers must be able to restore the previous immutable PLC configuration within maximum allowable downtime limits, preventing extended and costly production outages.
7. Enforce Strict Authorization and Dual-Person Approval Gates
To prevent insider threats or accidental administrative errors, high-risk changes affecting safety instrumented systems (SIS) or core supervisory control networks must require dual-person sign-off. Approval workflows should automatically route requests to lead automation engineers and security directors before any maintenance window opens, adding an extra layer of human verification.
8. Schedule Changes Around Deterministic Maintenance Windows
Industrial processes run on strict timing constraints where downtime translates to massive financial loss. Change execution must be strictly mapped to scheduled turnaround windows, planned plant outages, or low-production shifts. Unscheduled, ad-hoc changes during active production cycles must be strictly prohibited outside of verified emergency declarations to preserve continuous operational safety.
9. Capture Pre- and Post-Change Cryptographic Baselines
Configuration drift is a primary vector for silent industrial sabotage. Before a change is implemented, teams must record cryptographic hashes of existing PLC logic and device configurations. Immediately following the change, post-execution hashes must be verified to ensure no unauthorized files or malicious payloads were injected alongside the approved modification during the maintenance window.
10. Implement Real-Time Monitoring During Change Execution
During the active execution window, security operations centers and plant engineers must maintain heightened telemetry surveillance. Monitoring industrial protocols like Modbus, DNP3, and OPC UA ensures that engineers can instantly detect anomalous register writes, unexpected protocol errors, or unauthorized network scans occurring during maintenance, intercepting malicious activity immediately.
11. Archive Immutable Change Records and Audit Trails
Regulatory compliance mandates verifiable audit trails. Every step of the change lifecycle—from initial RFC submission and sandbox test results to final post-change hash verifications—must be logged in an immutable, tamper-proof repository. These detailed records serve as primary evidence during external audits for frameworks like NIS2 and NERC CIP, satisfying strict oversight demands.
12. Conduct Post-Implementation Reviews and Continuous Feedback Loops
The change control lifecycle does not end when the maintenance window closes. A mandatory post-implementation review evaluates whether the change met its operational goals without introducing performance degradation or security anomalies. Lessons learned from these reviews feed continuously into updating engineering baselines, refining risk models, and improving future maintenance predictability.
Integrating Advanced OT Visibility Solutions for Change Control
To automate and verify these complex change workflows, modern industrial enterprises deploy specialized continuous monitoring platforms. While established asset discovery tools from legacy vendors like Nozomi Networks, Dragos, Claroty, Shieldworkz, and TXOne provide essential network telemetry and baseline configuration tracking, advanced platforms bridge the critical gap between raw packet analysis and audit-ready change governance. By continuously monitoring device configurations and network behavior across Purdue levels zero through four, industrial organizations can instantly flag unauthorized modifications and ensure strict change compliance.
Conclusion
Creating an effective OT change control process requires a decisive shift away from flexible IT-style ticketing toward rigid, process-aware industrial governance. By integrating multi-disciplinary review boards, offline sandbox testing, cryptographic baseline tracking, and strict maintenance scheduling, organizations can balance the competing demands of plant agility and cyber-physical safety. Implementing these 12 structured steps transforms change management from a bureaucratic hurdle into a robust defense mechanism, protecting critical infrastructure against unauthorized modifications, regulatory non-compliance, and catastrophic operational downtime.